Roughly 5,000 people have access to AI systems the public has not seen, according to Andrej Karpathy, a founding member of OpenAI. In a post on X, he says everyone else has seen a preview, meaning the AI released to the public.
That preview has answered some small questions wrong. In one that spread online in February, a person asks whether to walk or drive to a car wash 50 meters away. The answer is drive, because walking leaves the car at home. When the company Opper tested 53 AI models, 42 said walk.
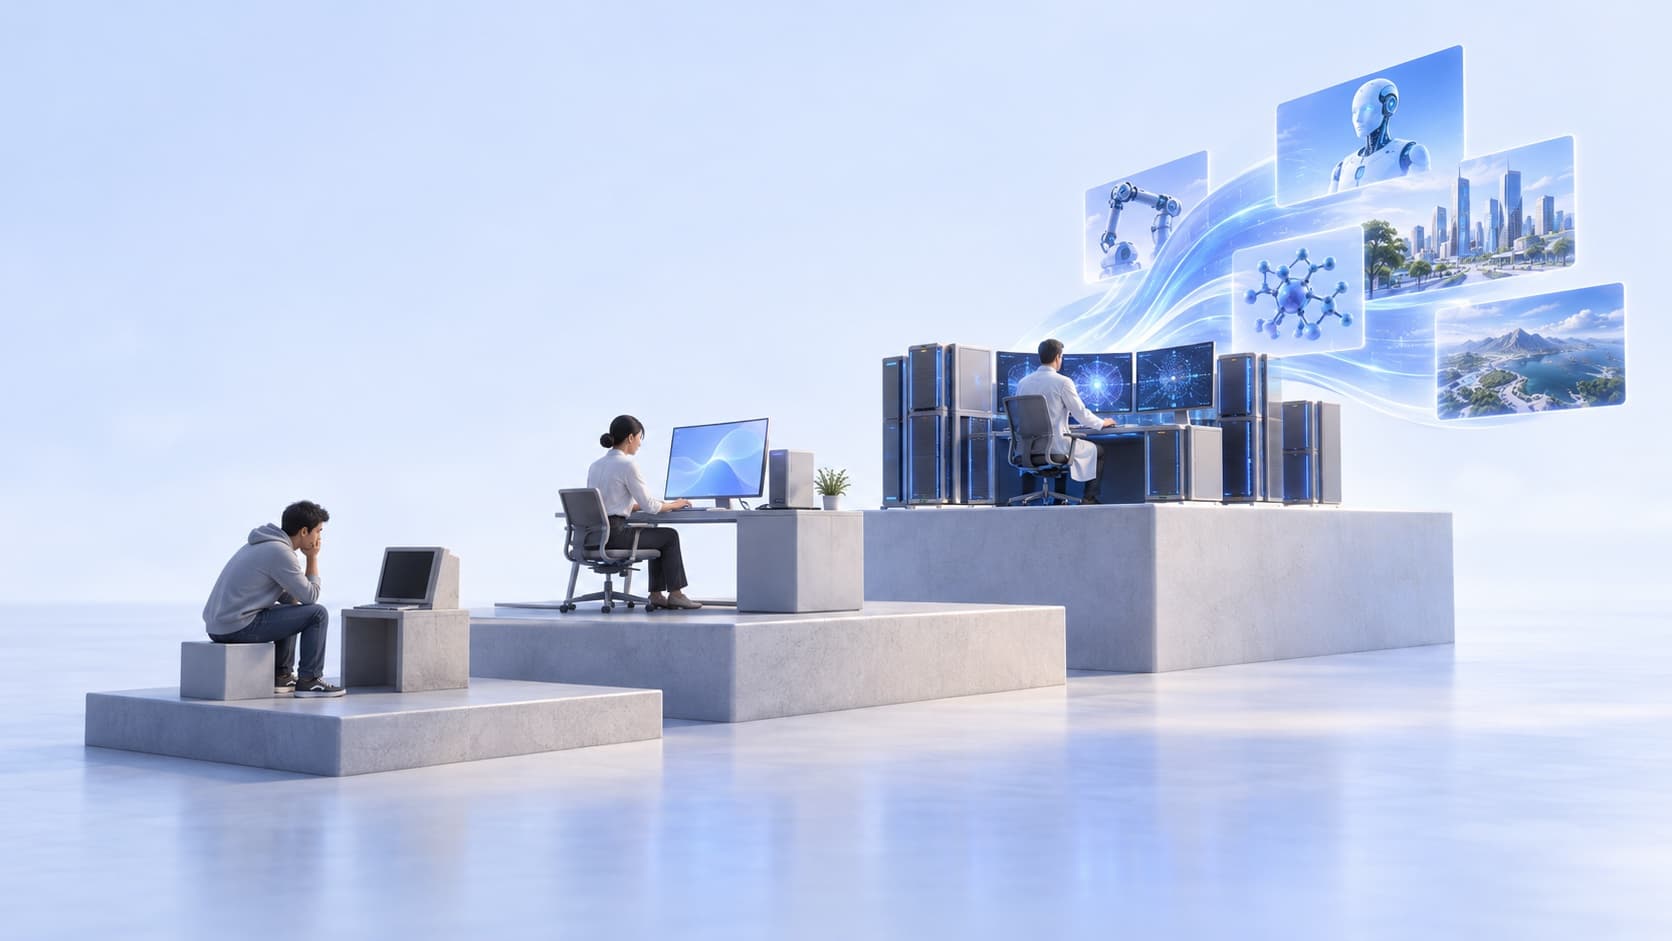
Karpathy’s post sorts the world into four groups. About 6 billion people have barely come in contact with AI. Another 1 billion to 2 billion use free chatbots now and then. A third group is about 20 million professionals in math and code who use top-tier models at work. For them, AI agents, programs that work through tasks on their own, finish projects that used to take weeks or months.
The fourth is the 5,000 inside the labs that build these systems. Karpathy describes their work as “swarms of thousands of agents collaborating over weeks” on software, security, science and mathematics.
Two labs have described results from systems the public does not use. In April, Anthropic said its unreleased Claude Mythos Preview model had found thousands of serious security flaws, including flaws in every major operating system and web browser.
In September, OpenAI said an internal model and about 10,000 agents had produced a proof. It concerns the Navier-Stokes problem, a question about the equations for how fluids move. The problem had gone roughly 90 years without a solution, and in 2000 the Clay Mathematics Institute named it one of seven Millennium Prize Problems. The institute does not list it as solved.
Karpathy’s word for this uneven picture, where skill varies by task, is jaggedness. He says AI is strongest in digital, valuable work where a program can check the answer. He traces that to training, because models learn from problems a computer can grade. Code runs or breaks, and a proof holds or fails, so a program can grade every attempt, while writing and advice are harder to grade.
Both labs report these findings themselves, and OpenAI describes its math results as being at different stages of checking. Karpathy offers his group sizes, the 5,000 included, as napkin math, a rough estimate.