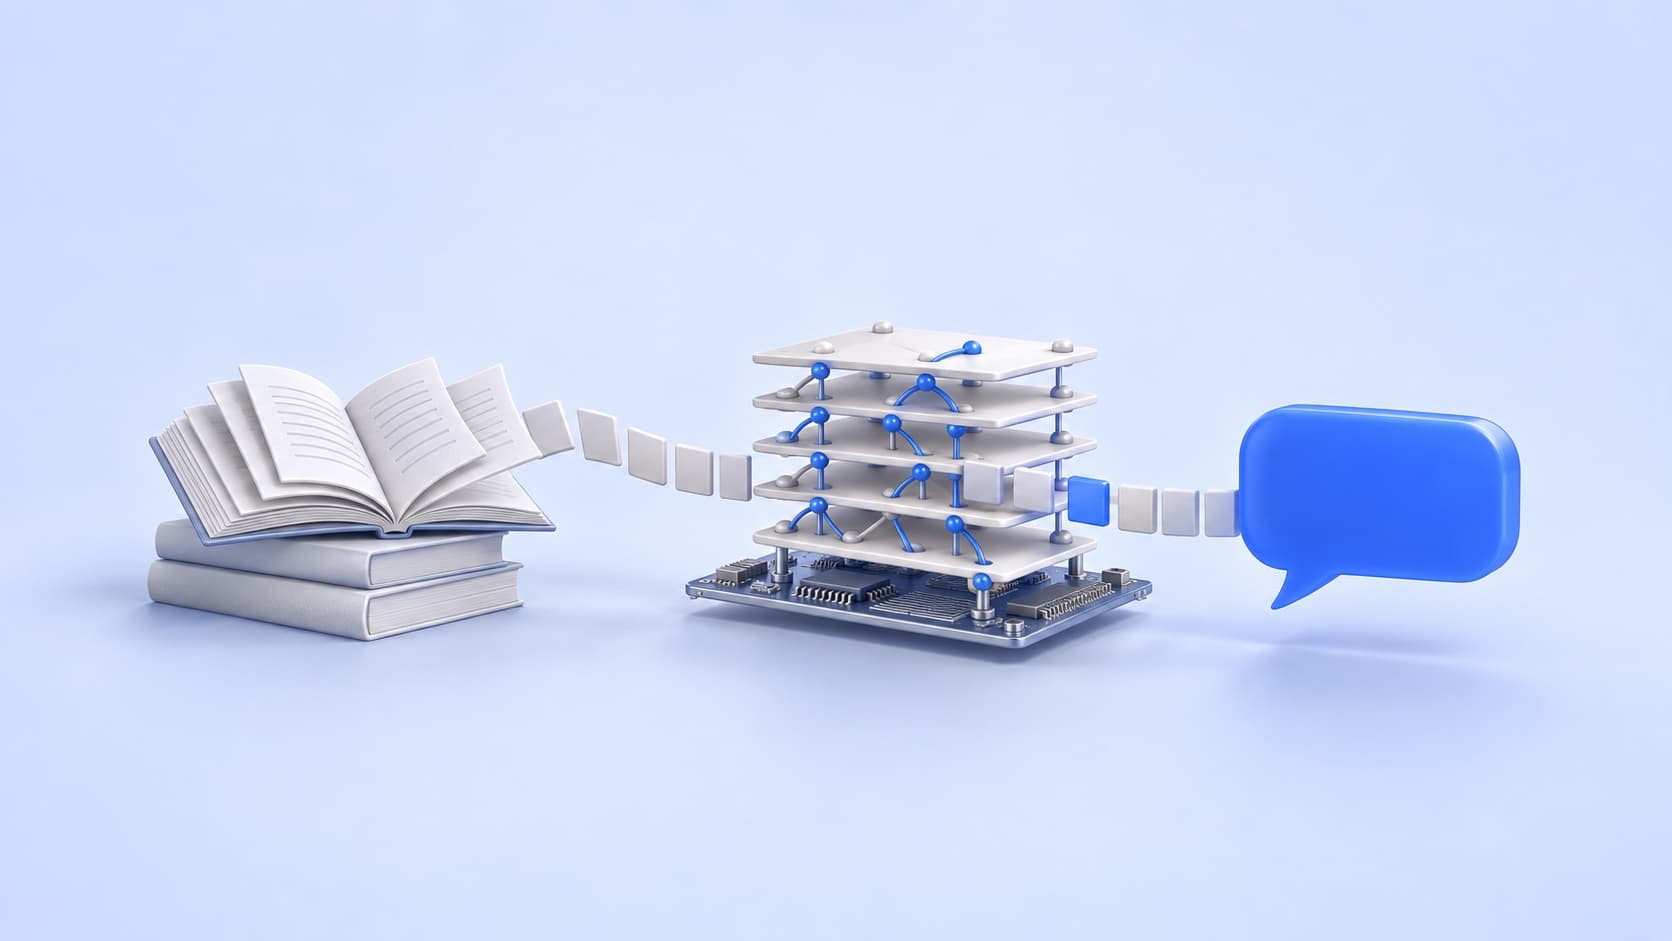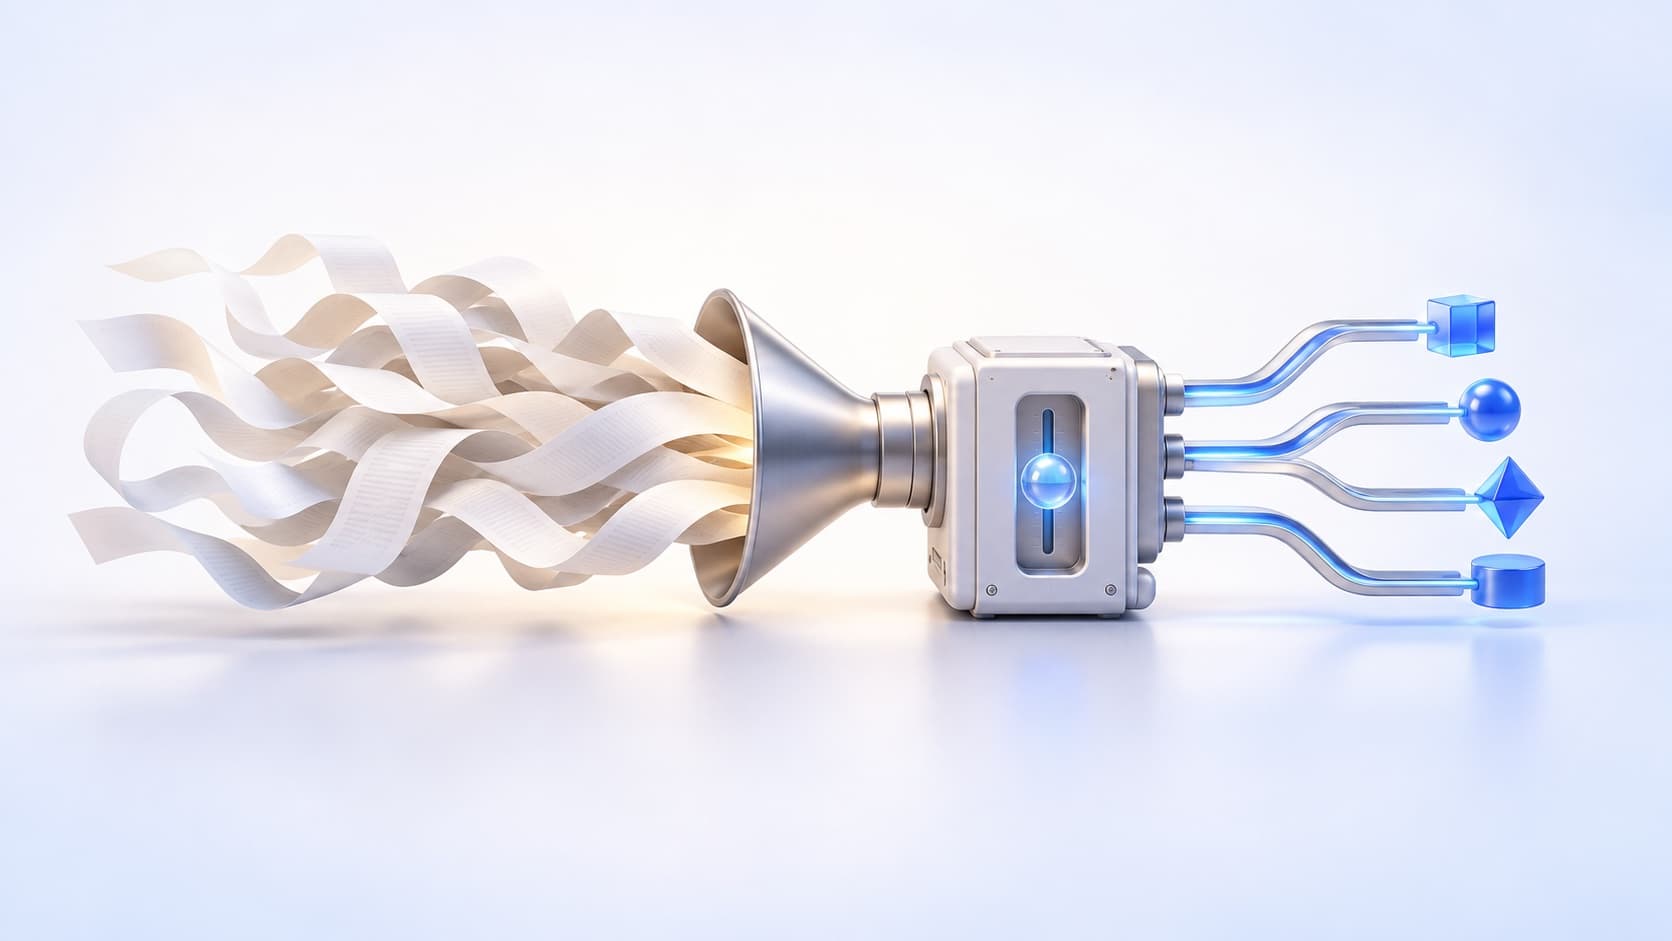
Jev, a model from TypeSafe AI, answers questions without writing a sentence. Given a support ticket and a few questions, the model returns a pick from a list, a score on a scale, or the probability of a yes. Production AI agents ask questions of this shape: whether a ticket is urgent, which model should handle a request, whether a command is dangerous.
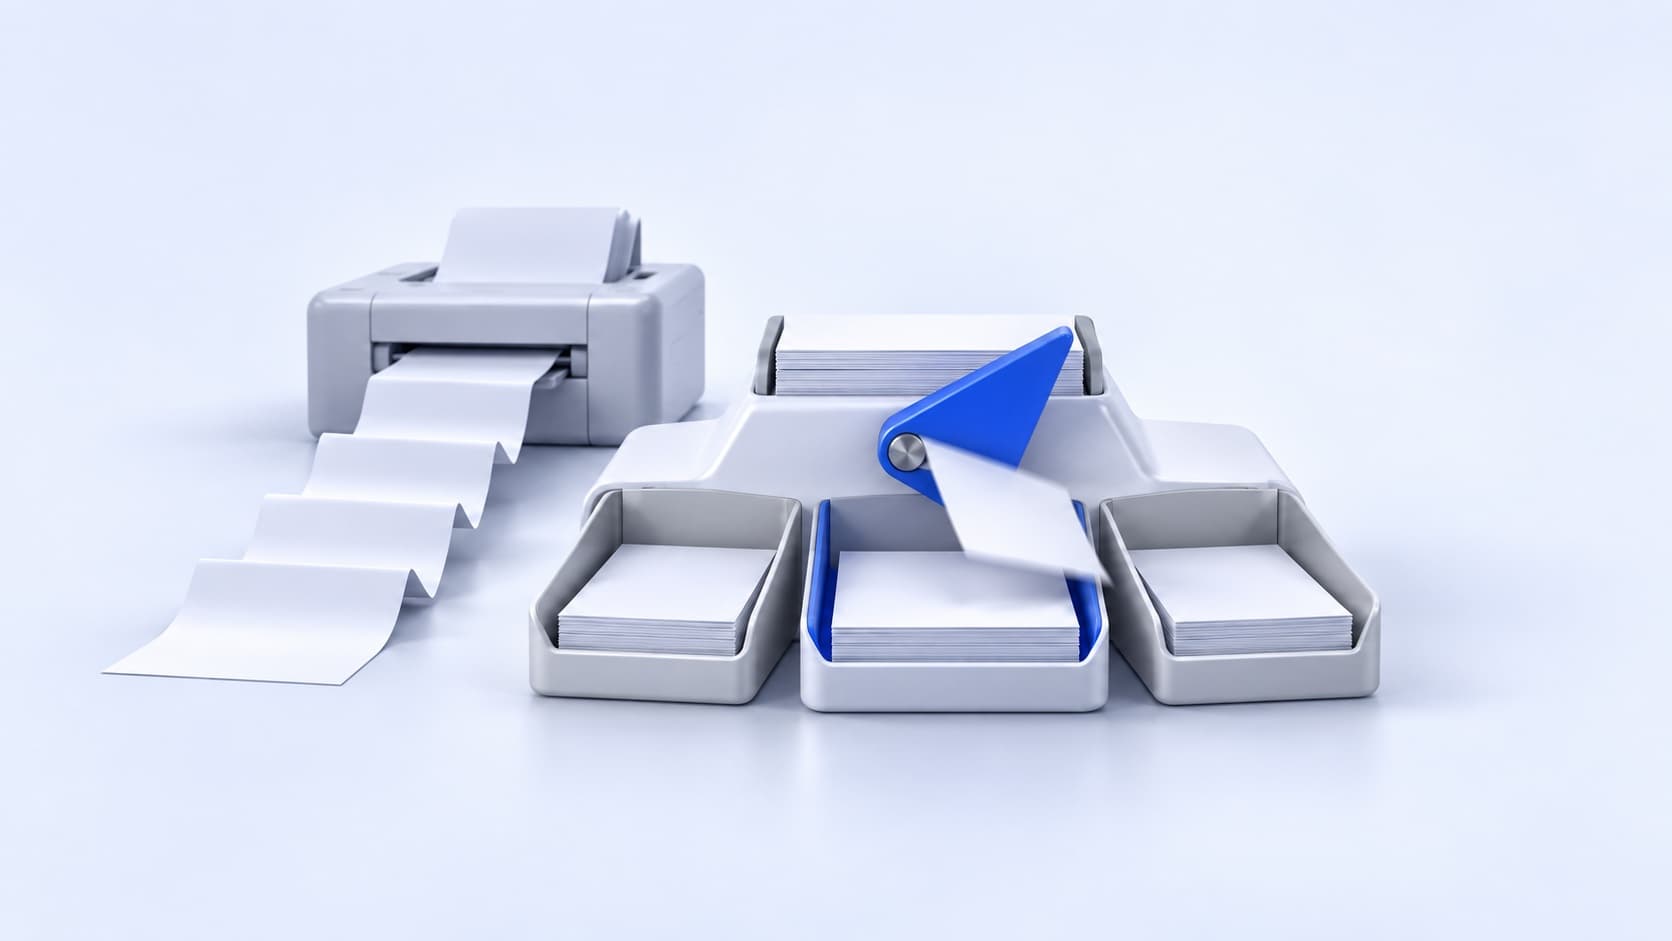
Sent to a frontier LLM, each question becomes a writing job. The LLM produces word fragments, called tokens, one after another while the agent waits. Code parses the text and retries when the format breaks. TypeSafe’s launch post puts LLM input between $0.20 and $10 per million tokens. Every output token, needed or not, costs about five times the input rate.
With Jev, the writing step disappears. Code keeps control of what happens next, and the model supplies common-sense judgment where hand-written rules break down. The allowed answers sit in the request, and the model handles every question at once, in a single pass. Most queries finish in about 100 milliseconds, per the company’s docs. Input costs $0.042 per million tokens, and output is free.
Each answer also carries a probability, and TypeSafe trains the model so higher confidence means higher accuracy, a property called calibration. LLMs tend to overstate their confidence when asked, the launch post reports. Free text lets an LLM invent an answer outside any list. Jev picks only from the options supplied, though the pick is sometimes wrong.
Moving decisions over starts small, with one job a frontier LLM handles, such as routing a ticket or blocking a risky command. The rubric of allowed answers comes first. Jev then answers alongside the LLM with no power to act, a setup called shadow mode. A log records each confidence score next to the real outcome.
Thresholds come from the log. The company’s confidence guide describes three bands: act automatically on high confidence, confirm or review in the middle, and hand low-confidence cases to a person. The safest decision goes automatic first, and more follow once the logged numbers hold.
An agent still sending every decision through a frontier LLM has an architecture problem. The fix splits the work across two models. The frontier LLM keeps planning, writing, and multi-step reasoning. Jev takes the routing, safety checks, scoring, and verification, and code decides what each answer triggers.