In company work, AI models have a size problem. The more information they are given at once, the more they lose key details and blur facts together. This decline is often called context rot, and it drives up computing costs and makes answers less dependable. Researchers at MIT have built a way around it, called Recursive Language Models.
Most teams respond by raising how much text a model can take in at one time, known as its context window. It seems like a clean fix, but bigger does not reliably mean better. What counts is how much of that text a model can use while still answering correctly, the core finding of a study called RULER.
A second study found that models are most likely to miss key information when it sits deep inside the text. A task that does not fit fails outright. Missed details lead to rework and cautious decisions, so the work gets slower and costlier while people still have to check the answers.
Summarising the documents first is the other common workaround, and it keeps requests small and costs predictable. But a summary strips out the specific details that decide whether an answer is correct. Teams either pay to include everything or save money and risk losing critical facts.
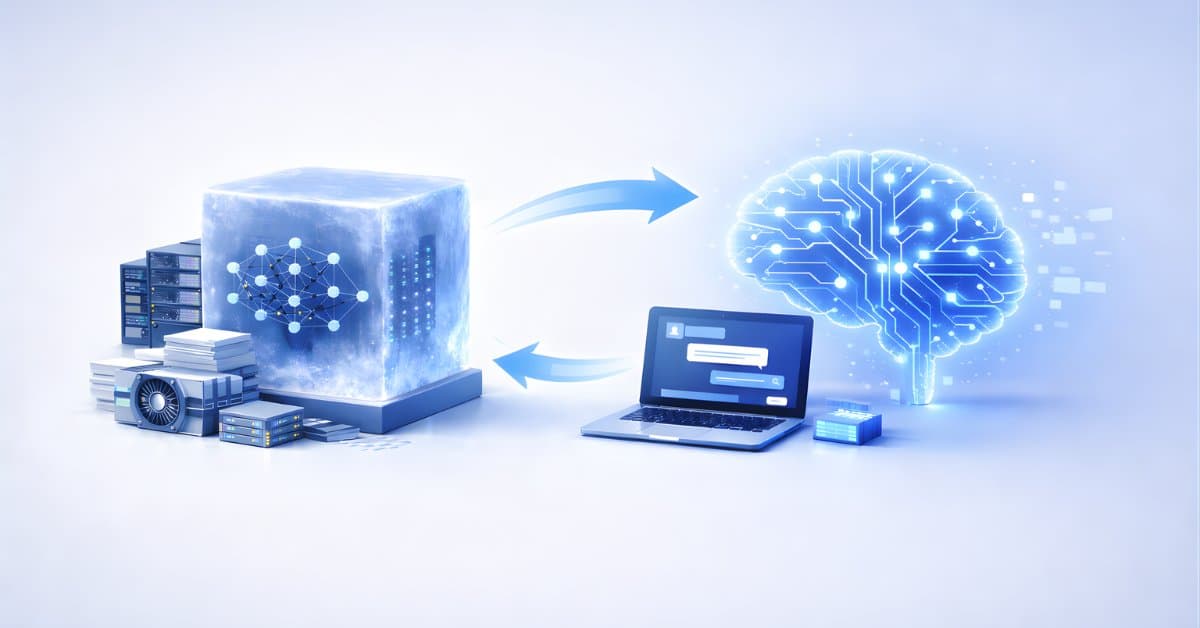
In MIT’s design, the documents stay outside the model, loaded into a workspace where it can run code. The model never reads the whole set in one go. It writes code to search the documents and pulls out the relevant sections whole, without squeezing them into a summary.
It can also hand slices of the reading to smaller copies of itself, which is what makes it recursive. The main model behaves like a project manager. It sets the plan, gives each smaller copy one slice to read and combines what they report. Each copy stays focused on its own slice instead of being swamped by the whole set.
MIT tested it on work that breaks standard methods, such as large tasks spanning many documents that are too big to feed in at once. The recursive version kept performing strongly and made those unwieldy jobs cost-effective.